C error tracking
Know when your C app breaks, before your users do
ForgeOps connects the errors your C app reports to the deploys, traces, and changes around them, so when production breaks, the incident already says who's affected, what changed, and where to look.
A fatal-signal handler is the only automatic capture story that exists in plain C; it writes a raw backtrace to disk before the process actually terminates. Running on ForgeOps' own dedicated infrastructure, so nothing about a C app's errors or its users' data gets routed through a third-party error-tracking vendor. See an incident investigated →
Install
# your own CMakeLists.txt
include(FetchContent)
FetchContent_Declare(forgeops_tracker
  GIT_REPOSITORY https://github.com/Luke-Popwell/forge-ops-tracker-c.git
  GIT_TAG v0.8.0)
FetchContent_MakeAvailable(forgeops_tracker)
target_link_libraries(your_app PRIVATE forgeops_tracker)

// main.c
#include <forgeops_tracker/forgeops_tracker.h>

int main(void) {
  forgeops_configuration_t *config = forgeops_tracker_configuration();
  forgeops_configuration_set_dsn(config, "https://<api_key>@getforgeops.net/api/v1/events");
  forgeops_tracker_install_handlers();
  forgeops_tracker_capture_error("ForgeOpsTestError", "Hello from the C SDK", NULL, NULL, 0, NULL, NULL, 0);
  forgeops_tracker_flush(); /* sends it now; a normal exit also does */
  return 0;
}
A fatal-signal handler is the only automatic capture story that exists in plain C; it writes a raw backtrace to disk before the process actually terminates.
Every client reports the same shape
Wherever it comes from, an event arrives with an exception class, a message, and a backtrace, plus whatever environment/release/server context that client can gather on its own. ForgeOps fingerprints and groups on the first three, so a C app's issues list works exactly the same way every other language's does: report the same bug a thousand times and it's still one row, not a thousand.
No agent, no sidecar: it's a plain HTTPS POST to ForgeOps' own ingestion API, so nothing about a C app's traffic gets routed through a third-party pipeline first.
Works with your framework
The C client hooks in at the framework level, not by wrapping individual calls, so nothing about how you already write C code has to change.
Fatal signals
SIGSEGV and friends are caught via sigaction, since C has no exceptions at all to hook.
Explicit capture
forgeops_tracker_capture_error reports right where you'd otherwise just log an error code.
What it looks like
The issue list
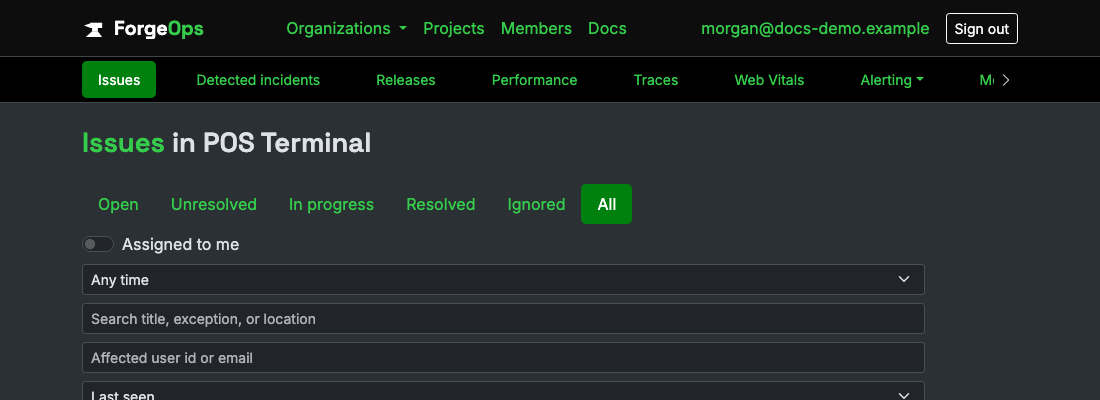
Every C issue reported into a project shows up here: title, status, assignee, event count, and when it was last seen, the same columns as any other language's project.
The issue detail
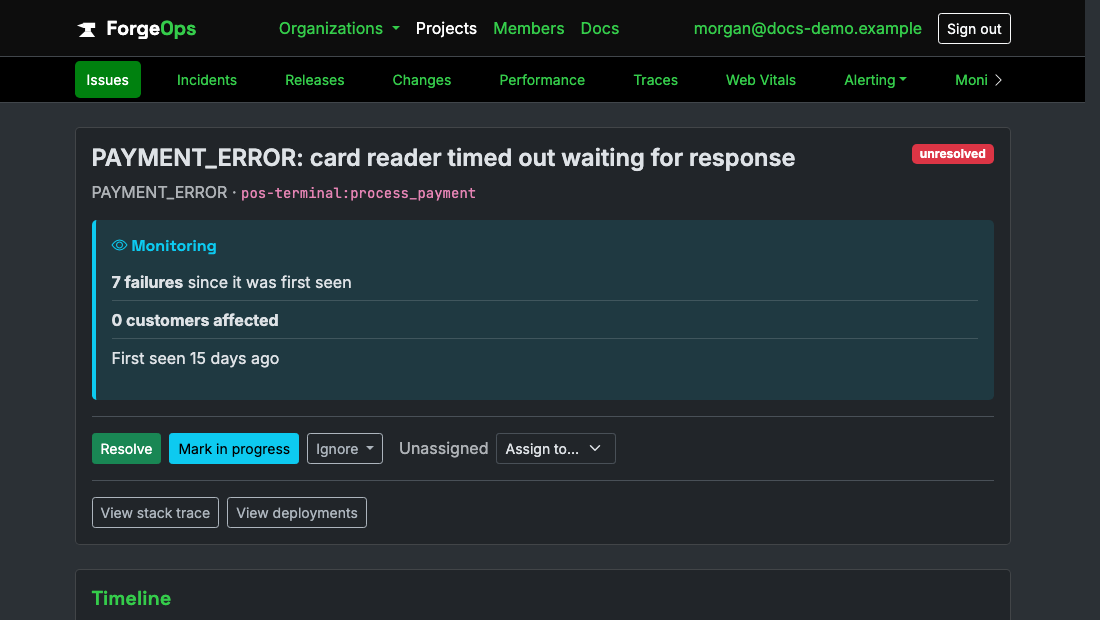
Every occurrence keeps its own timestamp, environment, release, and server, plus the backtrace exactly as C reported it, expandable per occurrence rather than flattened into one generic stack.
Alerting
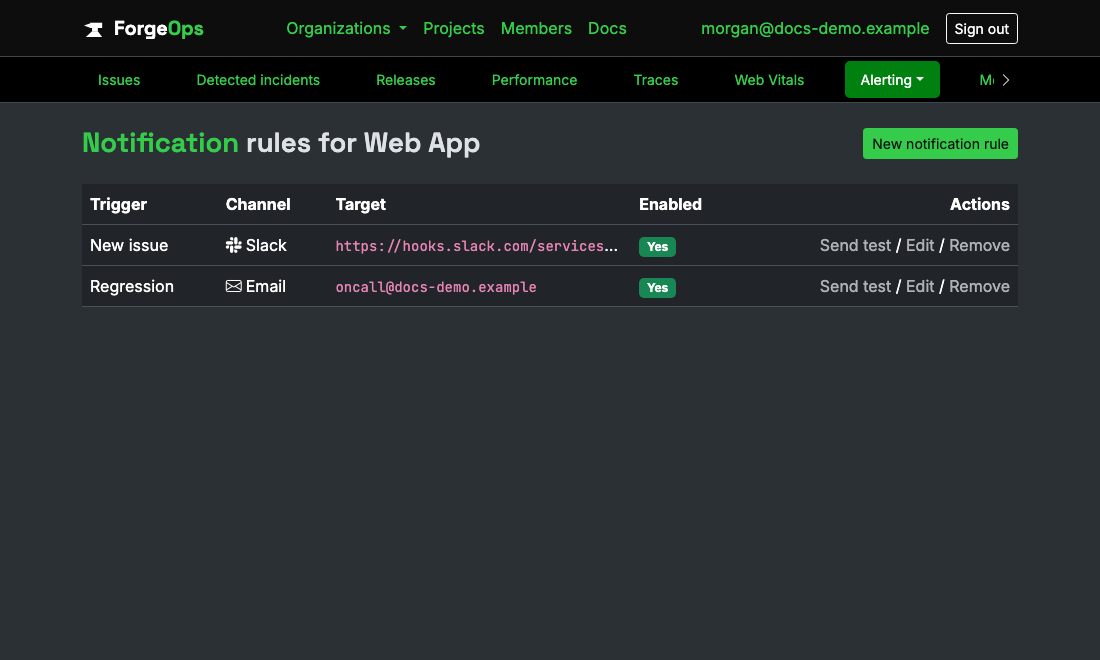
A new C issue, a regression, or a spike past a threshold you set can reach Slack, Microsoft Teams, email, PagerDuty, Opsgenie, or a generic webhook, configured per project, per trigger.
Heartbeats
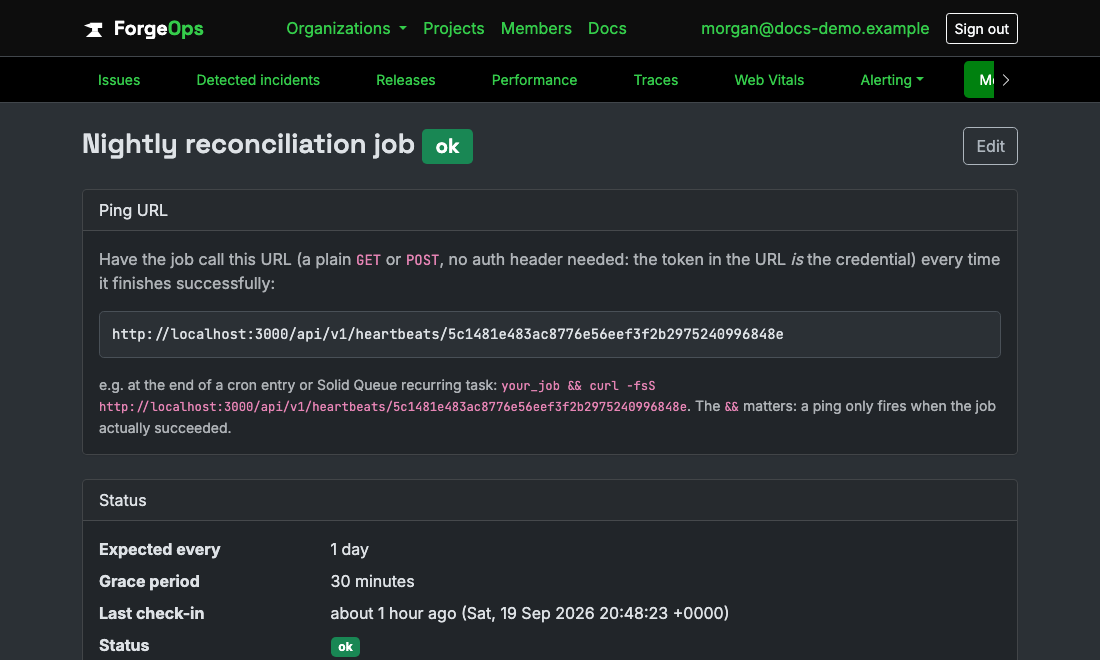
For the failure mode error tracking can't see on its own: a C cron job or recurring task that's supposed to run but silently stopped. Each heartbeat gets its own ping URL and its own grace period before it alerts.
Distributed tracing
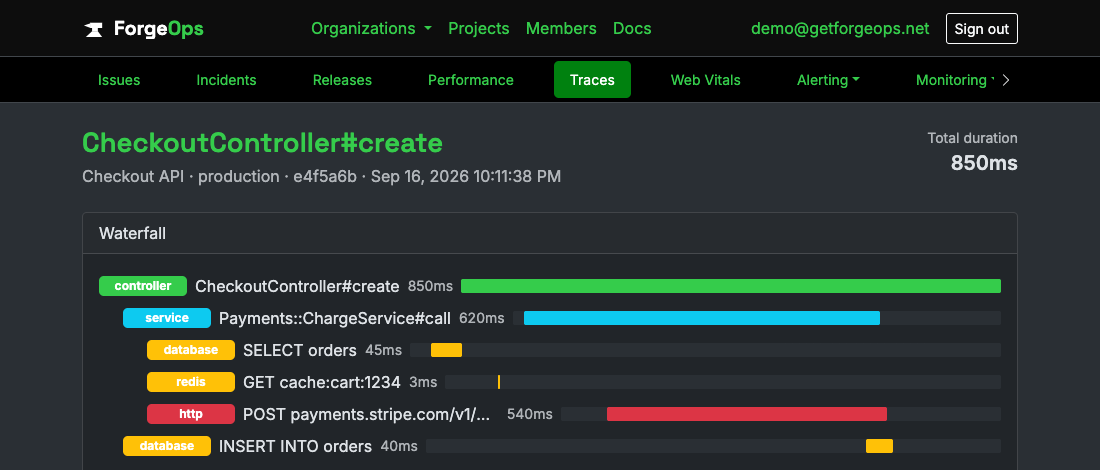
There is no web framework here, so you bracket the unit of work you want traced, and anything inside it on the same thread can add spans. Only a slow call's trace is ever sent: whether it crossed the threshold (one second by default, configurable) is decided entirely inside your process, so a fast call costs nothing over the wire. Requires a plan that includes distributed tracing.
forgeops_trace_t trace = forgeops_tracker_trace_start();

forgeops_span_t span = forgeops_tracker_span_start("charge card", "service");
charge(order);
const char *keys[] = {"order_id"};
const char *values[] = {"42"};
forgeops_tracker_span_stop_with_data(&span, keys, values, 1);

/* Something you timed yourself (started_at is wall-clock milliseconds since the epoch): */
forgeops_tracker_record_span("SELECT orders", "database", started_at_ms, duration_ms, NULL, NULL, 0);

forgeops_tracker_trace_stop(&trace, "GET /checkout");
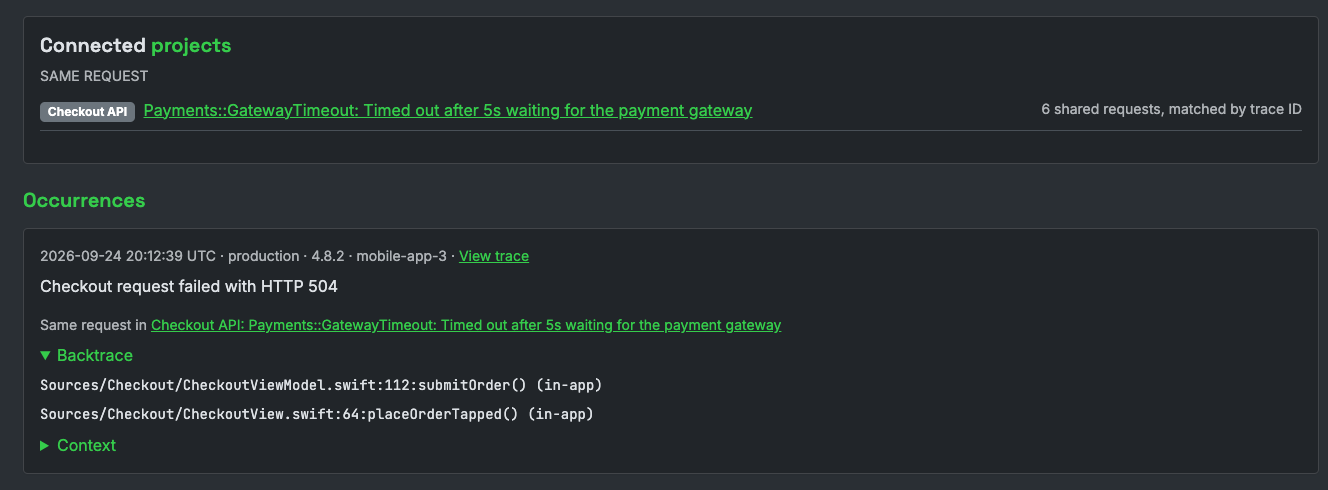
Bracket a request with forgeops_tracker_http_span_start and _stop and it's recorded as its own http span and handed the standard traceparent header, ready for libcurl, so the service you call nests its request under it. Start the trace with forgeops_tracker_trace_start_with_traceparent to continue the caller's trace instead. An error captured inside the trace carries its trace id: with the other service on the current ForgeOps server SDK and the two projects linked in ForgeOps, the failed checkout shows the API error from the very same request. Limit which hosts get the header with forgeops_configuration_set_trace_propagation_targets. Needs tag v0.4.0.
forgeops_trace_t trace = forgeops_tracker_trace_start_with_traceparent(incoming_traceparent); /* NULL starts a new one */

forgeops_http_span_t http = forgeops_tracker_http_span_start("POST", url);
struct curl_slist *headers = NULL;
if (http.header[0] != '\0') headers = curl_slist_append(headers, http.header);
curl_easy_setopt(curl, CURLOPT_URL, url);
curl_easy_setopt(curl, CURLOPT_HTTPHEADER, headers);
CURLcode result = curl_easy_perform(curl);
forgeops_tracker_http_span_stop(&http);
curl_slist_free_all(headers);

/* Carries this trace's id: */
if (result != CURLE_OK) forgeops_tracker_capture_error("CheckoutFailed", curl_easy_strerror(result), NULL, NULL, 0, NULL, NULL, 0);

forgeops_tracker_trace_stop(&trace, "POST /checkout");
SQL in a request
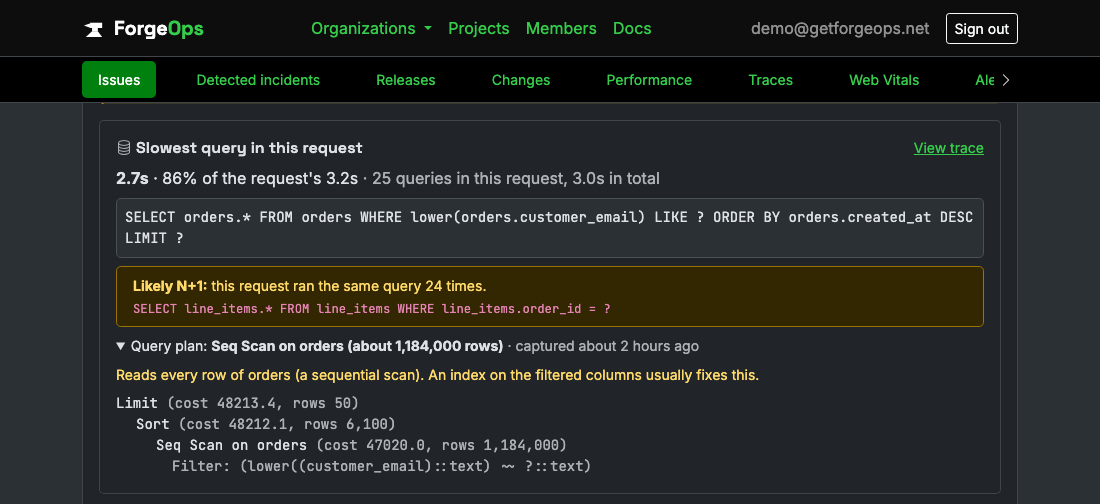
When the request an issue failed in was traced, the issue opens with its slowest query: how long it took, its share of the request's time, how many queries the request ran, and a likely N+1 warning when the same statement ran five or more times. This client doesn't instrument a database library, so stop a database span with forgeops_tracker_span_stop_with_sql and pass its SQL. The statement is masked before it leaves your process, every string and number replaced with a question mark, and the same SQL shows under that span's bar in the trace's waterfall. Needs tag v0.6.0, on a plan that includes distributed tracing.
const char *sql = "SELECT * FROM readings WHERE sensor_id = 42 AND label = 'boiler'";
forgeops_trace_t trace = forgeops_tracker_trace_start();

forgeops_span_t span = forgeops_tracker_span_start("Load readings", "database");
sqlite3_exec(db, sql, on_row, NULL, NULL);
forgeops_tracker_span_stop_with_sql(&span, sql, "sqlite", NULL, NULL, 0);
/* Sent as "SELECT * FROM readings WHERE sensor_id = ? AND label = ?" */

forgeops_tracker_trace_stop(&trace, "GET /readings");
What changed
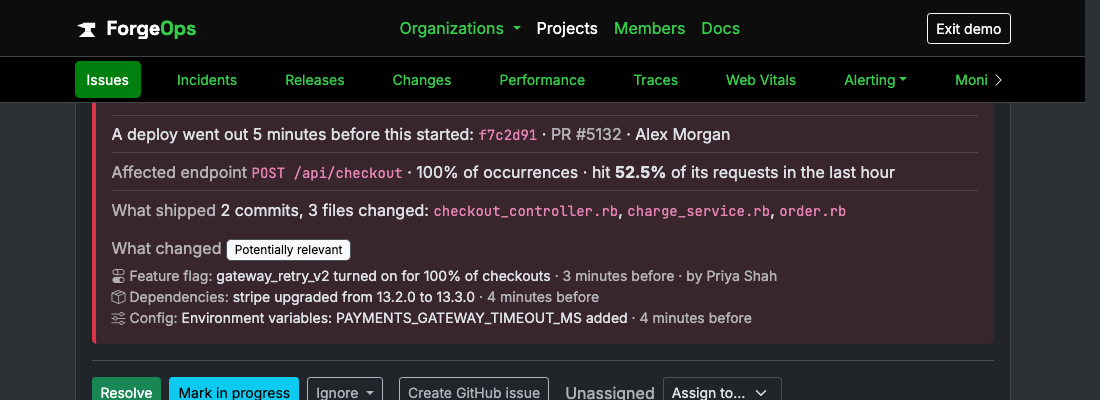
When a feature flag flips or a config value changes on a device or a server, record it from your flag client's callback, and it shows under What changed on any issue that starts in the next two hours, and on the project's Changes page beside your deploys, labeled potentially relevant, never as the cause. Every string is copied before the call returns; a background pthread delivers it, so the call never blocks on the network, and an atexit hook sends anything still queued. There's no automatic startup snapshot here; every change is one you record. Needs tag v0.5.0, on a plan that includes change tracking.
#include <stdio.h>
#include <forgeops_tracker/forgeops_tracker.h>

/* Your flag client's change callback, with the key and the new value */
static void on_flag_changed(const char *key, int enabled) {
  const char *keys[] = {"flag", "to"};
  const char *values[] = {key, enabled ? "true" : "false"};
  forgeops_change_options_t options = {.actor = "flag-service"};
  char title[256];
  snprintf(title, sizeof title, "%s turned %s", key, enabled ? "on" : "off");
  forgeops_tracker_record_change_with_options("feature_flag", title, keys, values, 2, &options);
}
Custom metrics and infrastructure monitoring
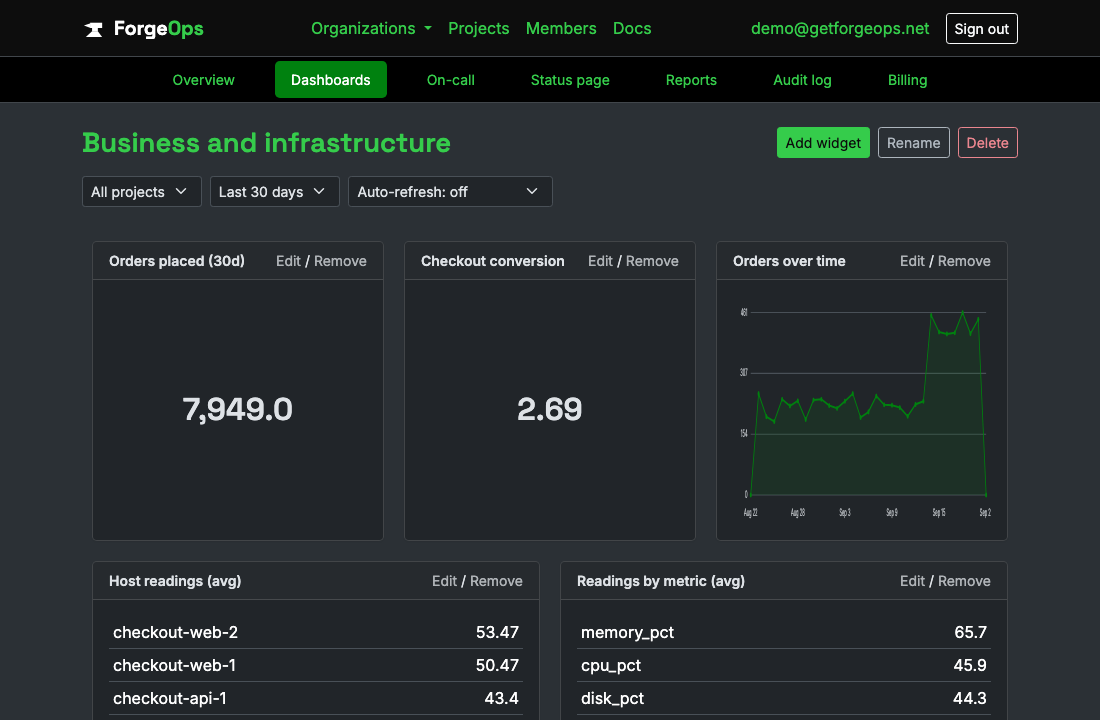
Track a business event you name yourself (a signup, a payment) or a reading from one of your own hosts, with one explicit call each; nothing is automatic. Pass the value explicitly: 1 for a bare counter, or a real amount (it can be negative, for a refund). A captured value is stored as its own row, so counts and sums you compute later are exact. Calls are buffered and flushed as one batch in the background, so they are safe to make inside a request, and flush_metrics sends whatever is buffered right now. A NULL hostname defaults to the configured server name. Requires a plan that includes custom metrics and infrastructure monitoring.
forgeops_tracker_capture_metric("signup", 1.0);    /* a bare counter */
forgeops_tracker_capture_metric("payment", 49.0);  /* a real magnitude; it may be negative (a refund) */

forgeops_tracker_capture_infrastructure_metric("cpu", 0.42, NULL);    /* NULL means config->server_name */
forgeops_tracker_capture_infrastructure_metric("disk", 0.81, "db-1");
forgeops_tracker_flush_metrics();                                     /* send right now */
Database errors
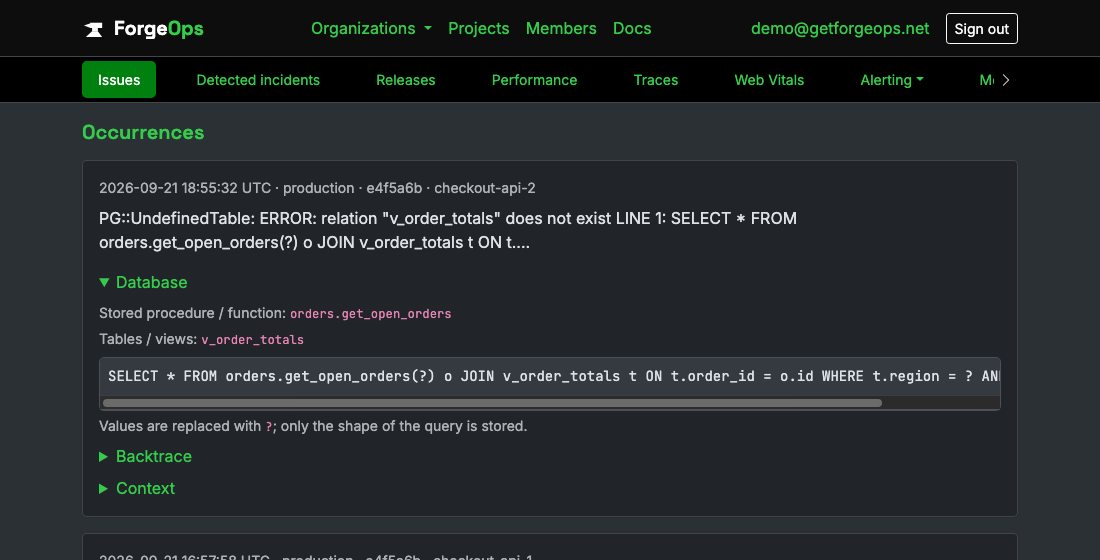
When an error comes from a database call, the issue shows which stored procedure, table or view its SQL touched, so you know where to start looking. C has no exception type that could carry SQL, so report the failure with forgeops_tracker_capture_error_with_sql where you ran the query. The names are sent by default and are identifiers, never values. The SQL statement itself is opt-in, with every string and number replaced by a question mark before it leaves your app, and a project setting can stop ForgeOps storing the statement at all.
const char *sql = "SELECT * FROM orders WHERE id = 42";
if (run_query(db, sql) != 0) {
    forgeops_tracker_capture_error_with_sql("DatabaseError", "query failed", sql,
                                            NULL, NULL, 0, NULL, NULL, 0);
}

// Opt in to also sending the masked statement (default 0).
forgeops_tracker_configuration()->capture_sql_statement = 1;
Questions
Do I need to change how I already handle errors?
Almost never. Every client hooks the framework's own exception handling directly, the same way the install snippet above shows, so your own logs, error pages, and rescue blocks keep working exactly as they did before, and ForgeOps just also finds out about it. The one common exception is a background-job runner that doesn't forward through that same mechanism on its own; that needs one small hook added instead, not a change to anything already there.
Where does the data actually go?
Straight to ForgeOps' own ingestion API over plain HTTPS. No agent, no sidecar, and no third-party ingestion service in between, so nothing about your app's traffic or its users' data gets routed through anyone else's pipeline first.
What happens if the same bug fires a thousand times?
It's fingerprinted from its exception class, message, and backtrace, so a thousand reports of the same bug still show up as one issue with an event count of 1,000, not a thousand separate rows to dig through. And a runaway loop can't use up your monthly event quota: once one issue repeats faster than your plan's hourly limit (50 an hour on Free), further repeats are still counted, and still count toward spike alerts, but they aren't stored or charged to your quota.
Is anything scrubbed before it's stored?
Yes. Emails, credit card numbers, and known API key/token formats are redacted out of every event before it's even written, on every plan, with room for per-project custom field names on top of the defaults.
Try it with your own C app
Free plan included, no credit card required. New organizations start with 14 days of Business.
Get started freeGet